An open weight model is an AI model whose trained weights are published, so you can download it and run it yourself instead of only reaching it through someone else's API. That gives you control: you can host it, customise it, test it and build on top of it.
What the weights are
A model like the ones behind chat assistants is a huge mathematical function. Most of it is made of numbers called weights (or parameters): the learned numbers inside the model. During training, those numbers are nudged again and again until the model gets good at its job. Everything it 'knows' about writing code, summarising notes or naming fish ends up stored in them.
So the weights are the expensive part. Training them can take enormous amounts of data and computing power. Once trained, though, the weights are just a set of files, often several gigabytes. Load them into the right software and the model runs.
API-only versus open weight
There are two common ways to get at a powerful model.
API only. The provider keeps the weights on its own servers. You send a prompt over the internet and get a reply. That is easy to start with, but the model is a black box: you can't see inside it, can't run it without the provider, and the provider decides what changes and when.
Open weight. The provider publishes the weight files, usually with code to load them and a licence saying what you may do. Now you can:
- Host it. Run it on your own laptop, server or cloud account.
- Customise it. Fine-tune it on your own data so it learns your domain.
- Test and audit it. Probe how it behaves, measure where it fails, and check it before you trust it.
- Build on top of it. Wrap it in your own app, shrink it to fit smaller hardware, or combine it with other tools.
Why that control matters
Open weight models are a good fit for:
- Privacy. Prompts and data never leave machines you control, which matters for medical, legal or company data.
- Local AI apps. A model on the device works offline and has no per-request bill.
- Experimentation. You can change settings, swap parts and try ideas a hosted API doesn't allow.
- Research. Researchers can study a model directly and repeat each other's results on the same weights.
Running one yourself: a worked example
Ollama is a popular free tool for running open weight models on your own computer. Once it is installed, two commands download a model and ask it a question:
ollama pull gemma3
ollama run gemma3 "Suggest three names for a fish"
The first command downloads the weights, once. The second loads them and generates a reply, entirely on your machine. Ollama also serves a small local API, so your own code can use the model the same way it would use a hosted one:
curl localhost:11434/api/generate -d '{
  "model": "gemma3",
  "prompt": "Suggest three names for a fish",
  "stream": false
}'
Nothing in either example leaves your computer.
Will it fit on my machine?
The size of a model's weights decides what hardware it needs. A rough rule: memory needed is about the number of parameters times the bytes used to store each one.
| Model size | 16-bit weights | 4-bit weights |
|---|---|---|
| 1 billion | about 2 GB | about 0.5 GB |
| 7 billion | about 14 GB | about 3.5 GB |
| 70 billion | about 140 GB | about 35 GB |
Running a model needs some memory on top of that, but the table shows why small models run on laptops and the biggest need serious servers. Storing each weight in fewer bits is called quantisation. It makes a model much smaller and faster, at the cost of a little quality, and it is how most people run open weight models at home.
Fine-tuning: teaching it your domain
Say Kitty runs a cat-supplies shop and wants a support assistant. A general model answers politely but doesn't know her return policy, her product names or the way her customers phrase things.
With an open weight model she can fine-tune it: carry on training it on a few thousand of her past support chats, so the weights shift towards her domain. Fine-tuning a whole large model is costly, so a common shortcut is LoRA (low-rank adaptation): the original weights are frozen and a small set of extra weights is trained alongside them. The result is a small add-on file instead of a full copy of the model.
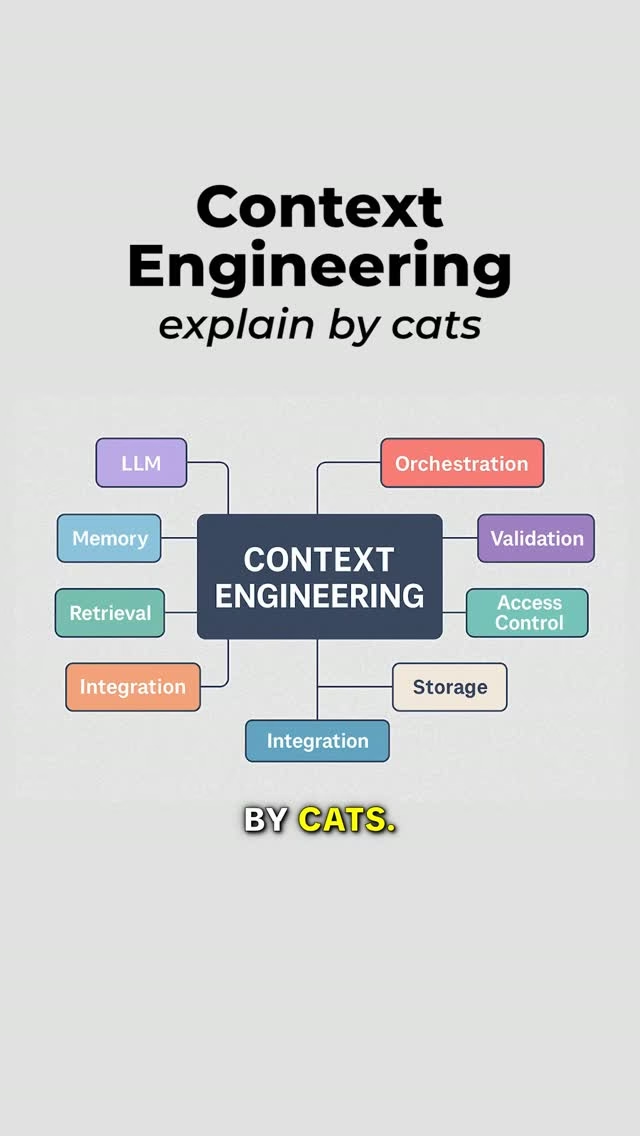
Fine-tuning changes how the model behaves, not what facts it can look up. For facts that change often, such as stock levels, it is usually better to give the model the right information in the prompt, which is part of AI engineering.
Open weight is not always open source
This is the part people mix up. 'Open weight' says the weights are available. It doesn't promise anything else. The weights may be available while the training data, the code or the licence still have limits:
- Training data. Often not released, and sometimes not even described in detail. Without it, nobody can rebuild the model from scratch or fully check what went into it.
- Training code. Sometimes shared, often not.
- Licence. Some models use standard open-source licences. Others use custom licences that restrict commercial use, limit how big a product can grow before needing a separate deal, or ban certain uses.
Open source, for software, means you get everything needed to study, change and rebuild it. The Open Source Initiative's definition of open source AI asks for the same idea: the weights, the code, and enough information about the data to recreate the model. Many popular 'open' models don't meet that bar, so the accurate term for them is open weight.
Common mistakes
- Skipping the licence. Open weight doesn't mean 'do anything'. Read the terms before you ship a product on it.
- Underestimating the hardware. Check the model size against your memory before you download 40 GB of weights.
- Assuming local means safe. A model on your laptop can still produce wrong or harmful answers. Test it on the job you need, just as you would a hosted one.
- Fine-tuning when a better prompt would do. Try clear instructions and examples first; fine-tune when that genuinely isn't enough.
Key takeaways
- Weights are the learned numbers inside a model; open weight models publish them.
- With the weights you can host, customise, test, audit and build on a model yourself.
- That makes open weight models great for research, privacy, experimentation and local AI apps.
- Model size and quantisation decide what hardware you need to run one.
- Open weight doesn't always mean open source: the training data, code or licence may still have limits.